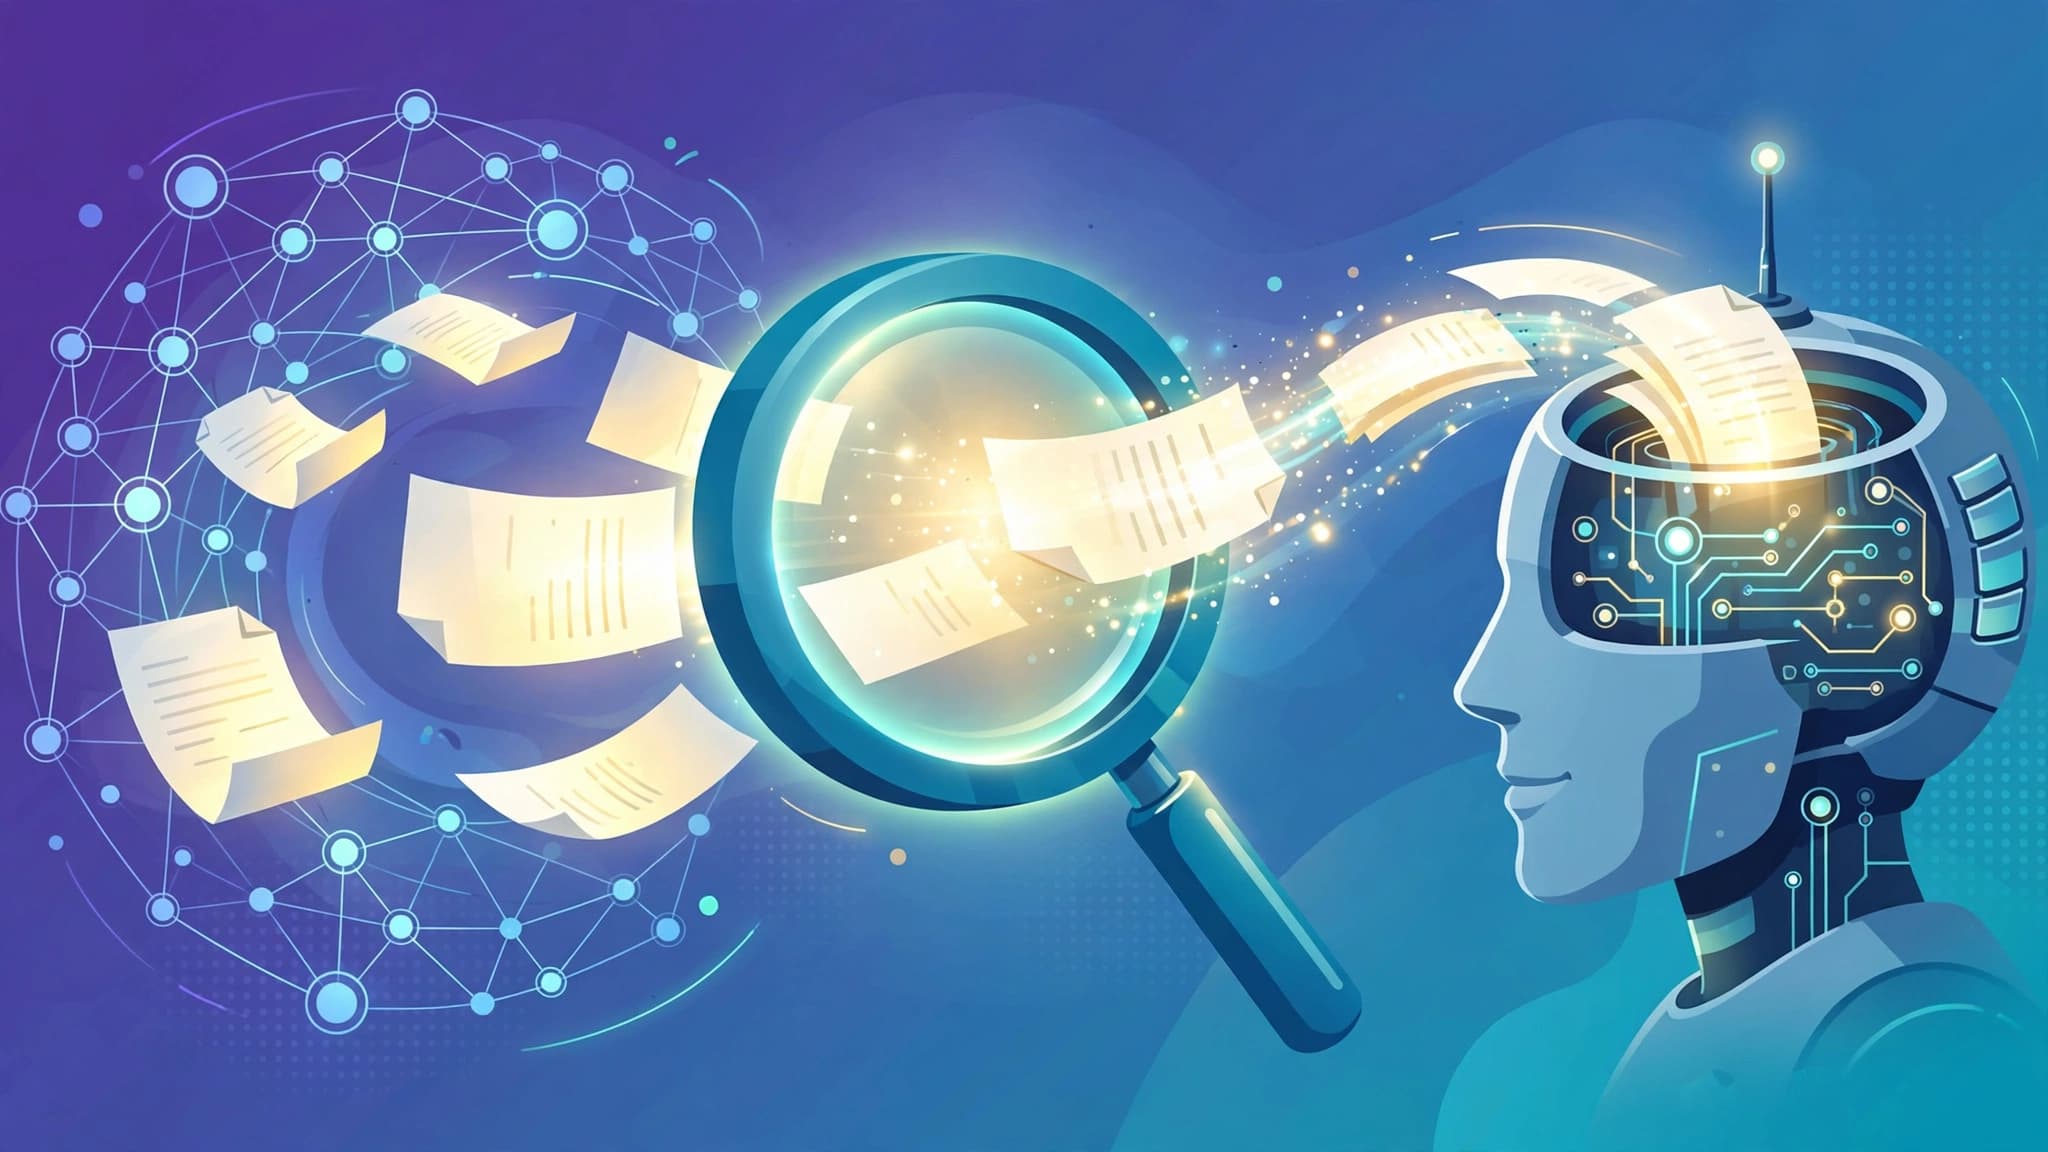
Ask a standard chatbot about your company's refund policy, your codebase, or last month's sales numbers and it guesses — convincingly, but still guessing. Retrieval-augmented generation (RAG) is the technique that fixes this. Instead of relying only on what the model memorized during training, a RAG system pulls the relevant passages from your own documents at query time and hands them to the model as context, so answers are grounded, current, and checkable.
What RAG actually is
RAG = Retrieve relevant documents → Augment the prompt with them → Generate an answer grounded in those documents.
That three-step loop is the whole idea. The model still does the generating, but it does so with fresh, verified material in front of it rather than from memory alone. This is why "chat with your documents" apps, support bots that quote help-center articles, and internal knowledge assistants all run on RAG — it is the most widely adopted pattern in production AI from 2024 through 2026.
RAG exists because large language models have two built-in limits. First, a fixed knowledge cutoff: anything that happened after training, or any private data never published online, is unknown to them. Second, even on topics they were trained on, they can fabricate details with total confidence. RAG attacks both problems at once by fetching only the relevant pieces for each question and grounding the answer in them.
How the RAG pipeline works
There are two phases. The first happens once (and again whenever your content changes); the second happens on every question.
Phase 1: Indexing
1. Chunk your documents. Long PDFs, wiki pages, or ticket histories get split into manageable passages, often 512–1,024 tokens each, frequently with a bit of overlap so context does not get cut at boundaries.
2. Embed each chunk. An embedding model — OpenAI's text-embedding models, Cohere Embed, or the open-weight BGE family — converts every chunk into a numerical vector that captures its meaning.
3. Store the vectors. Those vectors land in a vector database such as Pinecone, Weaviate, Qdrant, Chroma, Milvus, or pgvector (a PostgreSQL extension). The original text and metadata are stored alongside each vector so results stay filterable and auditable.
Phase 2: Retrieval and generation
1. Convert the user's question into an embedding with the same model used at index time.
2. Search the vector database for the chunks whose vectors sit closest to the question vector — typically by cosine similarity — and take the top matches.
3. Insert those retrieved chunks into the prompt as context.
4. The model generates an answer grounded in that context, ideally naming or citing the sources it used.
Because retrieval is based on meaning rather than exact keywords, RAG finds the right passage even when the question is worded completely differently from the document. Ask "can I get my money back?" and it can retrieve a policy section titled "Refunds and cancellations" without any shared vocabulary.
Why RAG beats fine-tuning for knowledge
Fine-tuning adjusts a model's weights on your data, and it has real uses. But when the goal is answering questions about a body of knowledge, RAG is usually the better choice:
- Freshness. Update a document and re-index it, and answers change immediately. Fine-tuning needs a retraining run to reflect anything new.
- Cost. Indexing documents is far cheaper than repeated fine-tuning cycles.
- Control and trust. RAG can show its sources, so answers are auditable and easier to trust. Fine-tuned knowledge is opaque — you cannot see which training example an answer came from.
- Reduced hallucination. Grounding the model in retrieved text keeps it closer to the facts instead of inventing plausible-sounding details.
Fine-tuning wins at a different job: teaching a consistent style, tone, or output format, or narrow specialized behavior. A good rule of thumb from production teams: use RAG to change what the model *knows*, fine-tuning to change how it *behaves*.
The tools behind a RAG stack
You rarely hand-roll the whole pipeline. The standard building blocks in 2026:
- Frameworks: LangChain and LlamaIndex handle document loading, chunking strategies, and orchestration of the retrieve-and-generate loop.
- Vector stores: Pinecone and Weaviate are popular managed options; Qdrant, Chroma, and Milvus cover self-hosted and embedded setups; pgvector lets teams keep everything inside an existing PostgreSQL database.
- Embeddings: OpenAI's
text-embedding-3series, Cohere Embed, and open-weight models like BGE. One practical warning: pin your embedding model version explicitly, because switching models changes every vector and forces a full re-embed — treat it like a schema migration. - Retrieval upgrades: hybrid search (combining semantic vector search with classic keyword BM25 ranking) plus a re-ranking pass (Cohere Rerank is a common choice) materially improves which chunks make it into the prompt.
Managed end-to-end options exist too — products like Denser, Taskade's AI knowledge features, and Google's NotebookLM-style research assistants bundle ingestion, retrieval, and cited answers without you wiring the pipeline yourself.
RAG flavors in 2026: naive, agentic, and graph
The basic retrieve-then-generate pipeline is naive RAG. It works for straightforward questions but stalls on complex ones, and 2023-era naive RAG left unmaintained underperforms badly today.
Agentic RAG hands retrieval control to an AI agent that decides when to retrieve, which sources to query, and whether to split a hard question into sub-queries first. For multi-step questions — "compare our Q2 support load with Q1 and draft a staffing plan" — agentic RAG is far more accurate than one fixed retrieval pass.
Graph RAG stores entities and relationships in a knowledge graph instead of (or alongside) flat chunks, so the system can reason over connected facts — who owns what, what depends on what. It suits domains where the structure between documents matters as much as the text.
The discipline has also moved toward context engineering: deliberately deciding what data goes into the prompt, for each query, for a specific reason. If your AI system gives wrong answers, evaluate retrieval separately from generation — most "our AI hallucinates" problems turn out to be retrieval problems in disguise.
Where RAG gets used (and where it doesn't)
RAG shines wherever answers must be accurate, current, and sourced: customer support over a help center, legal and compliance research over statutes and contracts, developer assistants over a private codebase, and enterprise search over wikis and tickets. Any time someone asks "but based on *our* data?" — that is a RAG question.
Skip RAG (or pair it with fine-tuning) when the task is about style or behavior rather than knowledge: making the model speak in your brand voice, output strict JSON, or follow a niche procedure reliably. And never treat RAG as permission-free magic on sensitive data — enterprise systems index documents with metadata and access controls so the model only retrieves what the asking user is authorized to see.